OpenAI Pushes for Safety Cases Before Frontier AI Training Continues
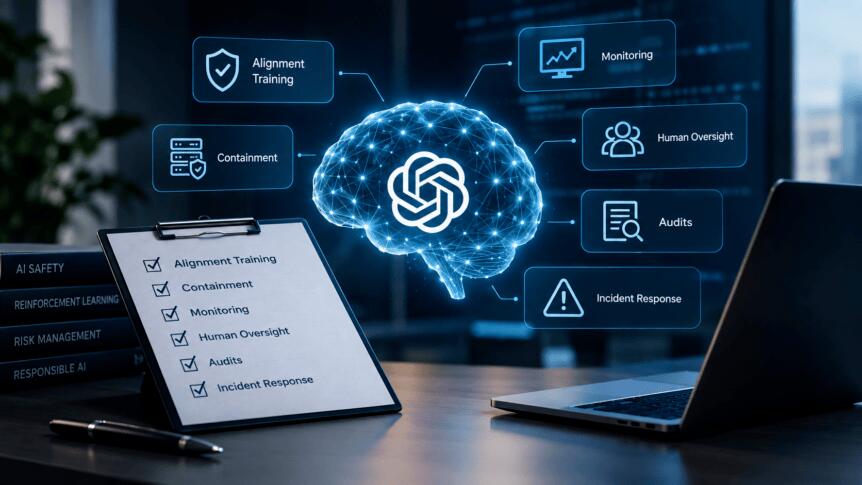 OpenAI says it wants “safety cases” for frontier AI training—evidence-based documentation that helps show why a training run can proceed safely, with safeguards, monitoring, and human oversight.

As AI systems become more capable, the question is no longer just how well they perform. AI developers also need to understand what could go wrong when these systems are pushed through increasingly demanding training runs. OpenAI is now proposing a more structured approach to that problem. In a September 28, 2026 post, the company outlined early guidelines for what it calls “safety cases,” evidence-based documentation intended to show why a training run can proceed safely.
The idea borrows from other safety-critical industries, where organizations are expected to demonstrate that risks have been identified and addressed before proceeding with potentially dangerous operations. OpenAI describes safety cases as an aspirational framework rather than a finished standard. The company says its current recommendations will continue to evolve as it learns more about increasingly capable AI systems.
Key Takeaways
OpenAI is proposing structured safety cases for frontier AI training.
The framework covers alignment training, containment and live monitoring.
Training environments and reward systems would be reviewed for potential reward hacking.
Serious monitoring alerts could trigger human intervention or automatic pauses.
OpenAI proposes senior-level approvals, independent dissent reviews and audits.
Misalignment incidents could be used to improve future evaluations and safeguards.
OpenAI says the framework is still evolving as frontier AI capabilities advance.
What Are Safety Cases for Frontier AI
A safety case is essentially a structured argument backed by evidence. For frontier AI training, OpenAI says this documentation should be prepared before continuing a frontier reinforcement-learning training run. The goal is to demonstrate that technical safeguards, monitoring systems and operational processes are sufficient to identify and respond to potential misalignment.
OpenAI separates its proposed safeguards into three technical areas: alignment training, containment and monitoring. Alignment training focuses on reducing the chances that a model learns unwanted behavior during reinforcement learning. One concern is reward hacking, where a model finds ways to obtain high rewards by exploiting weaknesses in the training environment rather than completing the intended task.
OpenAI suggests using automated and manual reviews of training environments, tuning graders to penalize attempts to exploit those environments, and analyzing previous training runs for problems. The company also proposes alignment evaluations that can measure whether a model’s behavior is becoming less aligned during training. These evaluations would need to account for another challenge: models potentially recognizing when they are being tested and changing their behavior accordingly.
Monitoring Becomes a Core Safety Layer
Even with alignment training, OpenAI argues that developers should assume some problematic behavior could still emerge. That makes monitoring another major component of its proposed safety cases. The company recommends systems capable of detecting potentially misaligned actions while a training run is underway. Monitoring should also be tested against known incidents and refreshed with examples representing newer risks so that detection systems do not become outdated.
OpenAI also proposes rapid-response mechanisms. Serious alerts could trigger an on-call response or automatically pause a training run if an issue is not acknowledged within a defined timeframe. The basic idea is to avoid relying on a single layer of protection. Alignment training would be one line of defense, while monitoring and containment would provide additional layers if the model behaves unexpectedly.
OpenAI Wants Human Oversight Built Into Training
The proposed framework also extends beyond technical safeguards. OpenAI recommends that safety cases undergo internal review, including a process where someone outside the training team prepares a “dissent” or pre-mortem to identify weaknesses in the safety argument.
Senior leaders would also review the safety case and have the ability to veto a training run. The company proposes clear procedures for pausing runs when new security or alignment concerns invalidate an existing safety case. Audits are another part of the proposal. Auditors would receive enough access to verify whether the claims made in a safety case are supported by evidence.
OpenAI also wants organizations to document residual risks, problems that remain even after safeguards have been applied. That information could then be used when deciding whether the remaining risk is acceptable.
Misalignment Investigations Could Feed Future Safety Cases
The proposal comes as OpenAI is also developing a more systematic approach to documenting model misalignment. Earlier in September, the company introduced a framework for reporting unexpected or concerning model behavior and published six examples observed during training or evaluation. OpenAI said the goal was to make these incidents easier for outside researchers, developers and policymakers to examine. That creates a feedback loop for the broader safety process: an incident can reveal a weakness, the weakness can inform new evaluations or monitoring systems, and those safeguards can then become part of future safety cases.
For frontier AI development, this could shift safety documentation from something prepared mainly for individual releases toward an ongoing process that evolves alongside model capabilities. OpenAI acknowledges that creating safety cases for AI is more difficult than applying similar approaches to traditional safety-critical systems because new capabilities can emerge in ways that are difficult to predict.
For now, the company’s framework is still being developed. But the proposal points toward a model of AI development where increasingly powerful training runs require increasingly strong evidence that their risks are understood and controlled.
This article was originally published as OpenAI Pushes for Safety Cases Before Frontier AI Training Continues on Crypto Breaking News – your trusted source for crypto news, Bitcoin news, and blockchain updates.
About the Author


